SIGNAL65 TCO Report

What does AI infrastructure really cost?

From GPU pricing to storage, networking, and efficiency—compare the true cost of running AI workloads between hyperscalers and CoreWeave Cloud.

Validated results

CoreWeave delivers leading performance and lower TCO for AI workloads

This important Signal65 study details a comprehensive TCO analysis of AI cloud deployments. It compares CoreWeave to general-purpose hyperscalers—across compute, storage, networking, orchestration, observability, and support—showing how the right cloud platform fundamentally improves AI efficiency, performance, and total cost for training and inference.

Up to
52
%
Lower TCO on NVIDIA HGX B300

over 3 years

Up to
65
%
Per-token cost/performance advantage

running DeepSeek-R1

Up to
26
%
Lower Serverless Inference Cost

Across 17 models

Left
Right
TCO report highlights

A 3-year TCO analysis of AI cloud infrastructure

This comprehensive report by Signal65 evaluates the true cost of running AI for small, medium, and large workloads, comparing CoreWeave with leading hyperscaler cloud providers. The findings show how purpose-built AI infrastructure can deliver significantly lower costs and greater efficiency over time.

No hidden costs

CoreWeave provides transparent, predictable pricing with no surprise charges for data transfer, API calls, or orchestration.

Full-stack efficiency

CoreWeave delivers efficiency at every layer of the full stack—across compute, storage, networking, and observability—with direct-to-expert support.

Performance-fueled savings

Higher GPU utilization, industry leading performance, and lower cost per token for inference reduces total cost at scale.

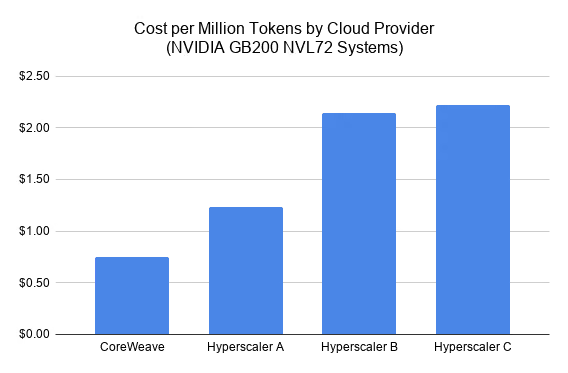
CoreWeave's bare-metal stack of compute, storage, and networking delivers higher performance and lower cost per token for inference than the hyperscalers we evaluated. Lower GPU pricing and the removal of data egress and storage request fees compound that advantage, delivering up to 65% lower three-year TCO on NVIDIA GB200 NVL72.
A 3-Year TCO and Tokenomics Analysis of AI Cloud Deployments – September, 2026
Side-by-side comparison

General-purpose hyperscalers vs. CoreWeave Cloud

CoreWeave Cloud enables greater efficiency, simpler deployment, and lower total cost at scale

General Purpose

Hyperscalers

  • Built for general-purpose computing
  • Optimized for breadth and flexibility
  • Modular services (compute, storage, networking all separate)
  • Lower average utilization (MFU ~35–45%)
  • Fragmented storage tiers (object + expensive high-performance layers)
Purpose-built for AI

CoreWeave Cloud

  1. Built specifically for AI workloads
  2. Optimized for training and inference at scale
  3. GPU, storage, and networking designed to work together
  4. Higher utilization (MFU 50%+)
  5. Storage designed for AI access patterns
Left
Right
Total cloud costs

A deep-dive economic and tokenomics analysis of AI cloud

To evaluate one key aspect of the TCO analysis, Signal65 modeled performance of NVIDIA GB200 inference performance and the cost per million tokens served. CoreWeave delivered the lowest cost per million tokens and achieved a per token savings ranging from 39% to 66% compared to the other hyperscalers.

Next steps

Get the most from your AI investment

Request a TCO Consultation

Explore flexible capacity plans

Pricing overview

Left
Right
Trusted by leading AI labs, platforms, and enterprises

Zoho
cohere
Altum
Mistral AI logo
Google
Jane Street logo
Decart logo
Rev.com logo
Cloudflare
Abridge logo
Chai logo
Fireworks AI logo
Augment logo
Conjecture logo
inflection ai
NovelAI logo
Runway logo