Are you paying for more model than the task requires?
Many teams start with a frontier model because it is the fastest way to get a new task working. Once the task is stable and volume grows, that same model may provide more capability than the job needs, while charging for the difference on every request.
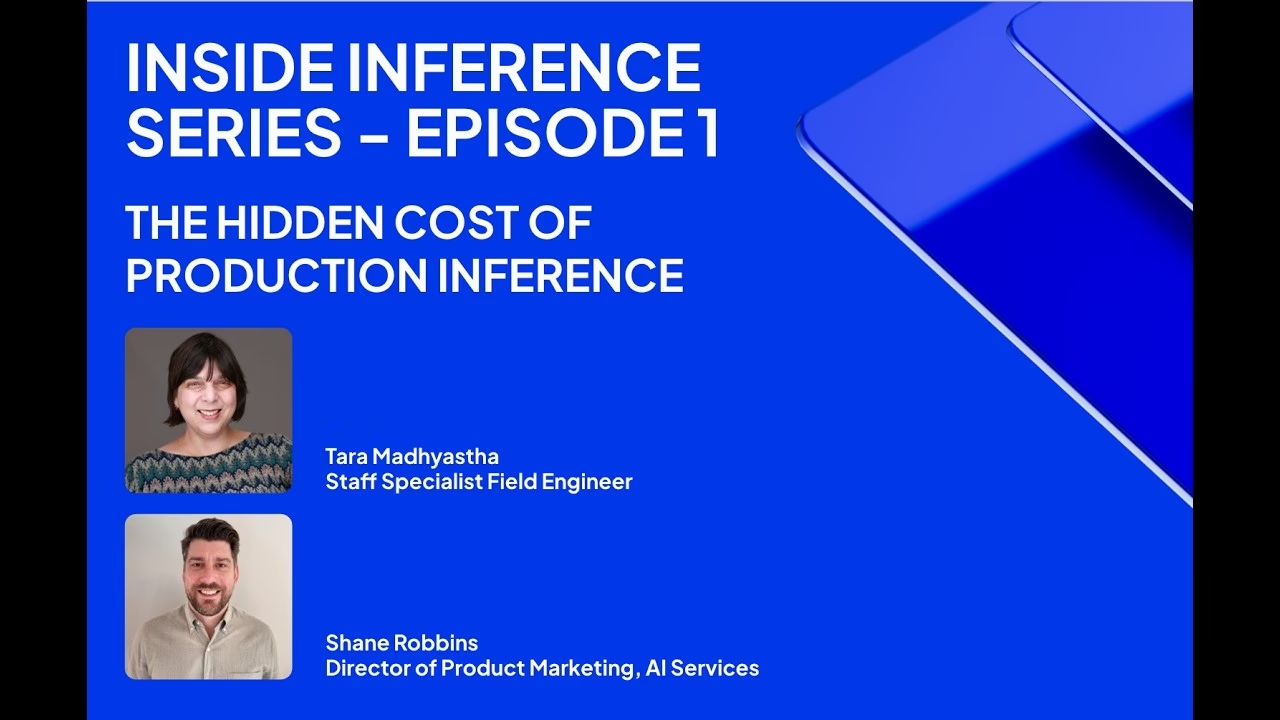
Watch this on-demand session to learn how to qualify a workload before training, identify where distillation or reinforcement learning fits, and evaluate whether a smaller, better-fit model can meet the quality bar your task requires.
You’ll also see a guided model-distillation workflow that moves from production traces and teacher relabeling through student training, held-out evaluation, and staged deployment. The walkthrough uses one approval-classification workload from the model already in production through a distilled student taking a share of traffic.
In this webinar, you’ll learn:
- How to identify bounded tasks where specialization may be a fit, including classification, extraction, structured output, tool calling, and narrow agent loops
- Why prompting first helps establish the task and quality bar, and why a documented no can be a productive result
- How model distillation and reinforcement learning differ, and when each approach may make sense
- How production traces become datasets through a collect, relabel, distill, evaluate, and ship workflow
- How held-out production inputs, per-example failures, and a permanent reference stream support more defensible rollout decisions
- What to watch for in a guided distillation demo, including teacher relabeling, parallel student training, and evaluation results
Bring one expensive, repeatable production task and use its real workload to evaluate a smaller candidate before moving traffic.