We hope you enjoy the session!

Video
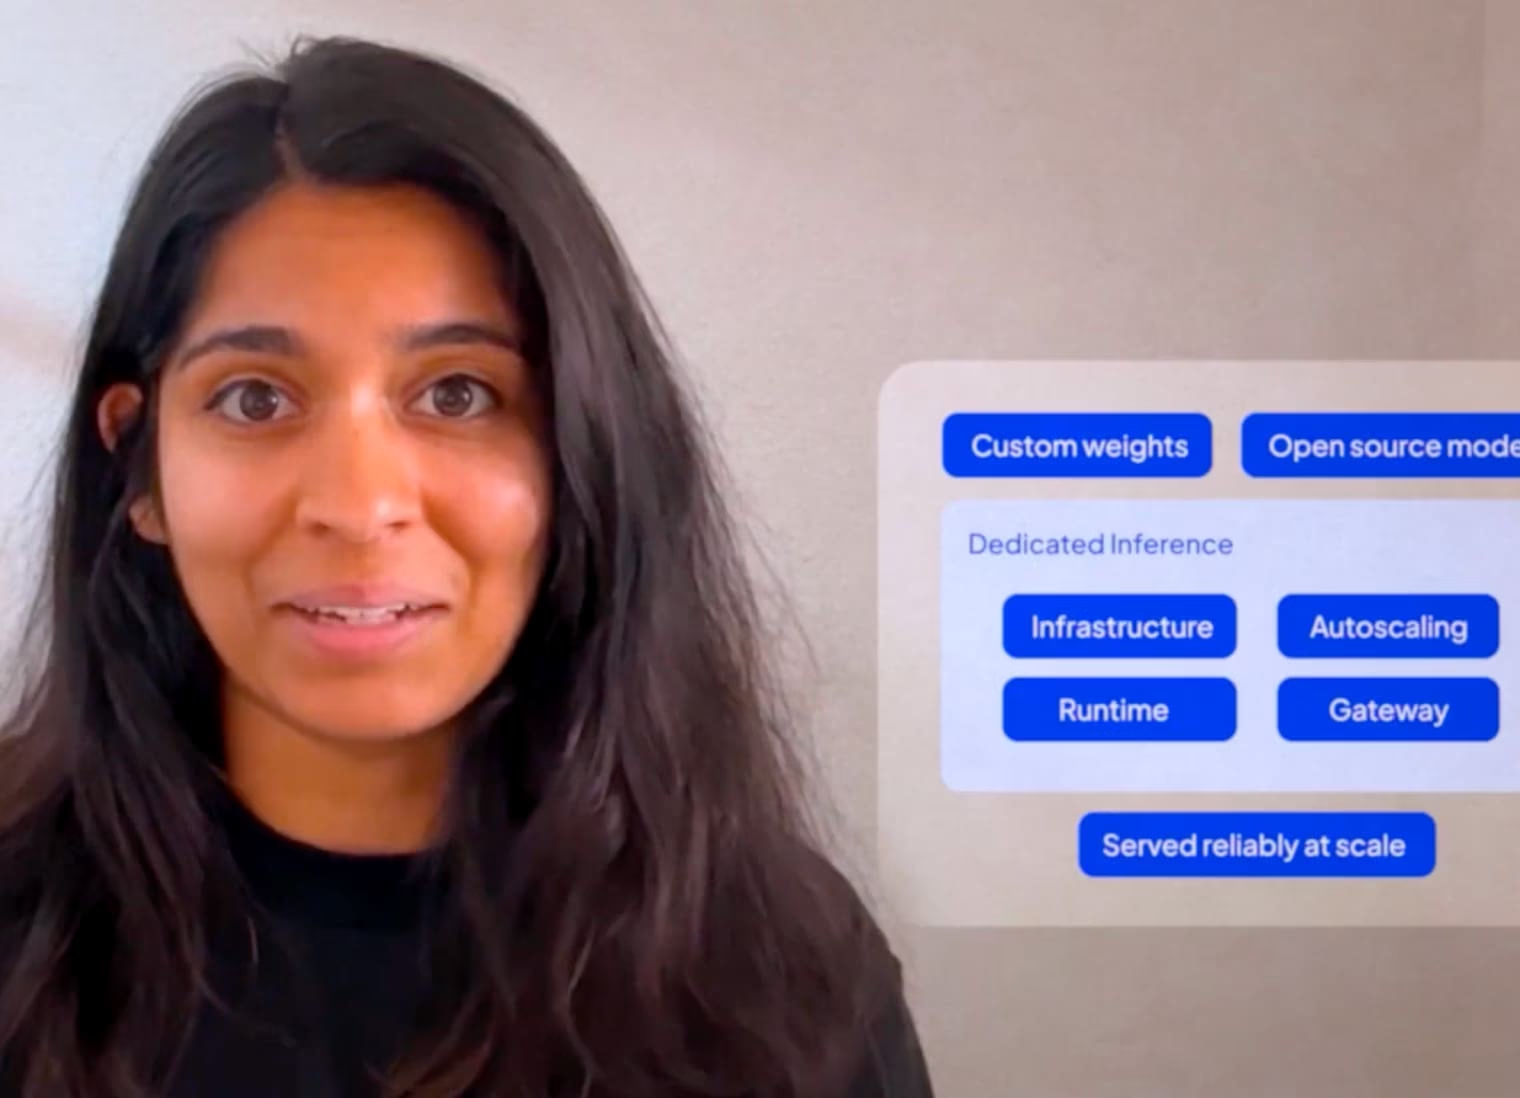
Dedicated Inference Demo
See how Dedicated Inference takes model weights from setup to a live, observable endpoint using a gateway, deployment, and dedicated GPUs.
We hope you enjoy the session!


At today's scale, managing AI training across disconnected Slurm and Kubernetes environments creates overhead that slows model progress and reduces GPU utilization. In this 30-minute briefing, we explored how CoreWeave's SUNK eliminates the research-to-production gap - and how SUNK Anywhere extends that unified operating model across on-prem, hybrid, and cloud environments.


Get the latest CoreWeave updates, AI breakthroughs, and insider perspectives from pioneers shaping the next generation of innovation.