As AI rapidly shifts toward long-context reasoning and autonomous agentic workflows, access to purpose-built, rack-scale acceleration has become essential for maintaining low-latency performance and viable unit economics.
Today, CoreWeave is excited to announce that the NVIDIA Vera Rubin NVL72 platform is in limited availability on CoreWeave Cloud. NVIDIA Vera Rubin is a generational leap in accelerated computing designed and built to power every phase of AI. With hundreds of NVIDIA Rubin GPUs deployed across multiple regions, CoreWeave has started onboarding customer workloads in production, including Cognition, which is seeing a 4.8x increase in total token throughput.
Customers can now access Vera Rubin NVL72 capacity to accelerate their agentic AI journey. This empowers teams to scale compute-heavy training, execute high-throughput agentic inference with ultra-low latency, and seamlessly manage end-to-end AI pipelines for production and continuous improvement across CoreWeave Kubernetes Service (CKS), CoreWeave Inference, CoreWeave SUNK, CoreWeave AI Object Storage, and CoreWeave Mission Control®.
Cognition advances autonomous software engineering on NVIDIA Vera Rubin NVL72
Cognition, creator of Devin, is the first customer to bring production agentic AI workloads to NVIDIA Vera Rubin NVL72 on CoreWeave Cloud.
Devin is an autonomous AI software engineer that works alongside development teams to complete complex, end-to-end assignments. Its work can span entire code repositories and involve extended chains of reasoning, code generation, debugging, execution, evaluation, and iteration.
To power Devin's computationally demanding lifecycle, Cognition embodies the AI loop by running both model training and production inference on the same bare-metal CoreWeave Cloud platform across several key areas:
- Production Inference Serving: Serving real-time agentic queries globally via CoreWeave Inference with low latency and high throughput.
- Inference Optimization: Collaborating directly with CoreWeave performance engineers to fine-tune KV cache management, serving parameters, and runtime configurations.
- Experiment Tracking: Utilizing Weights & Biases Models to monitor and evaluate experiments across training runs.
- Model Training, Fine-Tuning & Reinforcement Learning: Closing the loop by running large-scale pre-training, fine-tuning, reinforcement learning (RL) post-training, and test-time scaling directly on Devin models to continually improve model performance.
Having scaled from initial bridge capacity to thousands of GPUs for training and dedicated inference on CoreWeave, Cognition's engineers ran production workloads within days of rack handover without requiring custom bring-up work of their own.
Agentic coding is an unforgiving workload that requires long contexts, high concurrency, and rapid reasoning. By deploying the NVIDIA Vera Rubin NVL72 on CoreWeave, our engineers are seeing up to a 4.8x increase in total token throughput for SWE-2 inference workloads over GB200 NVL72. For an agentic workload where every step waits on the last one, that compounds into real work Devin gets done. CoreWeave continues to deliver the bleeding-edge rack-scale acceleration we need to push the boundaries of AI.
Silas Alberti, SVP Research & Founding Team of Cognition
Validating Vera Rubin performance with real-world agentic workloads
The NVIDIA Vera Rubin NVL72 is a unified, liquid-cooled platform engineered as a single logical GPU, integrating 72 Rubin GPUs, connected as one with NVIDIA NVLink 6, and 36 Vera CPUs. With 1,400 TB/s of HBM4 memory bandwidth and 216 TB/s NVLink Bandwidth, this new platform is able to handle trillion-parameter models while scaling rollouts at a 45x lower token cost vs Blackwell.
These capabilities are particularly important for agents. Agents do not simply generate a single response: they repeatedly reason, retrieve context, invoke tools, execute code, evaluate outcomes, and try again. Faster processing at each stage can compound across the entire workflow, helping agents complete more useful work in less time and at a lower cost.
Building on our initial benchmark proving Vera Rubin NVL72’s superior power efficiency, we partnered with Cognition to evaluate how these gains translate to production-style agentic workloads. Their engineering team conducted independent benchmarks on CoreWeave comparing the new Vera Rubin NVL72 platform against previous-generation NVIDIA GB200 NVL72 baselines.
Cognition’s SWE-2 benchmark results
The results show a massive leap in how effectively Vera Rubin can sustain both inference and training for tasks using SWE-2, Cognition's latest generation of autonomous AI software engineer:
- 4.8x increase in total token throughput for SWE-2 inference: Agents like Devin repeatedly read vast codebases, reason, and execute code in a continuous loop. The Vera Rubin NVL72 delivered a 4.8x jump in total token throughput, meaning Devin can ingest dense context and output solutions significantly faster, compounding time-savings across every step of a complex engineering task.
- 3.8x boost in output token throughput for Reinforcement Learning (RL): To continually improve Devin’s performance, Cognition relies heavily on generating massive volumes of trial-and-error reasoning trajectories during post-training. A 3.8x increase in output generation directly accelerates these RL workloads, allowing Cognition's research team to iterate on new model weights and push updates to production much faster.
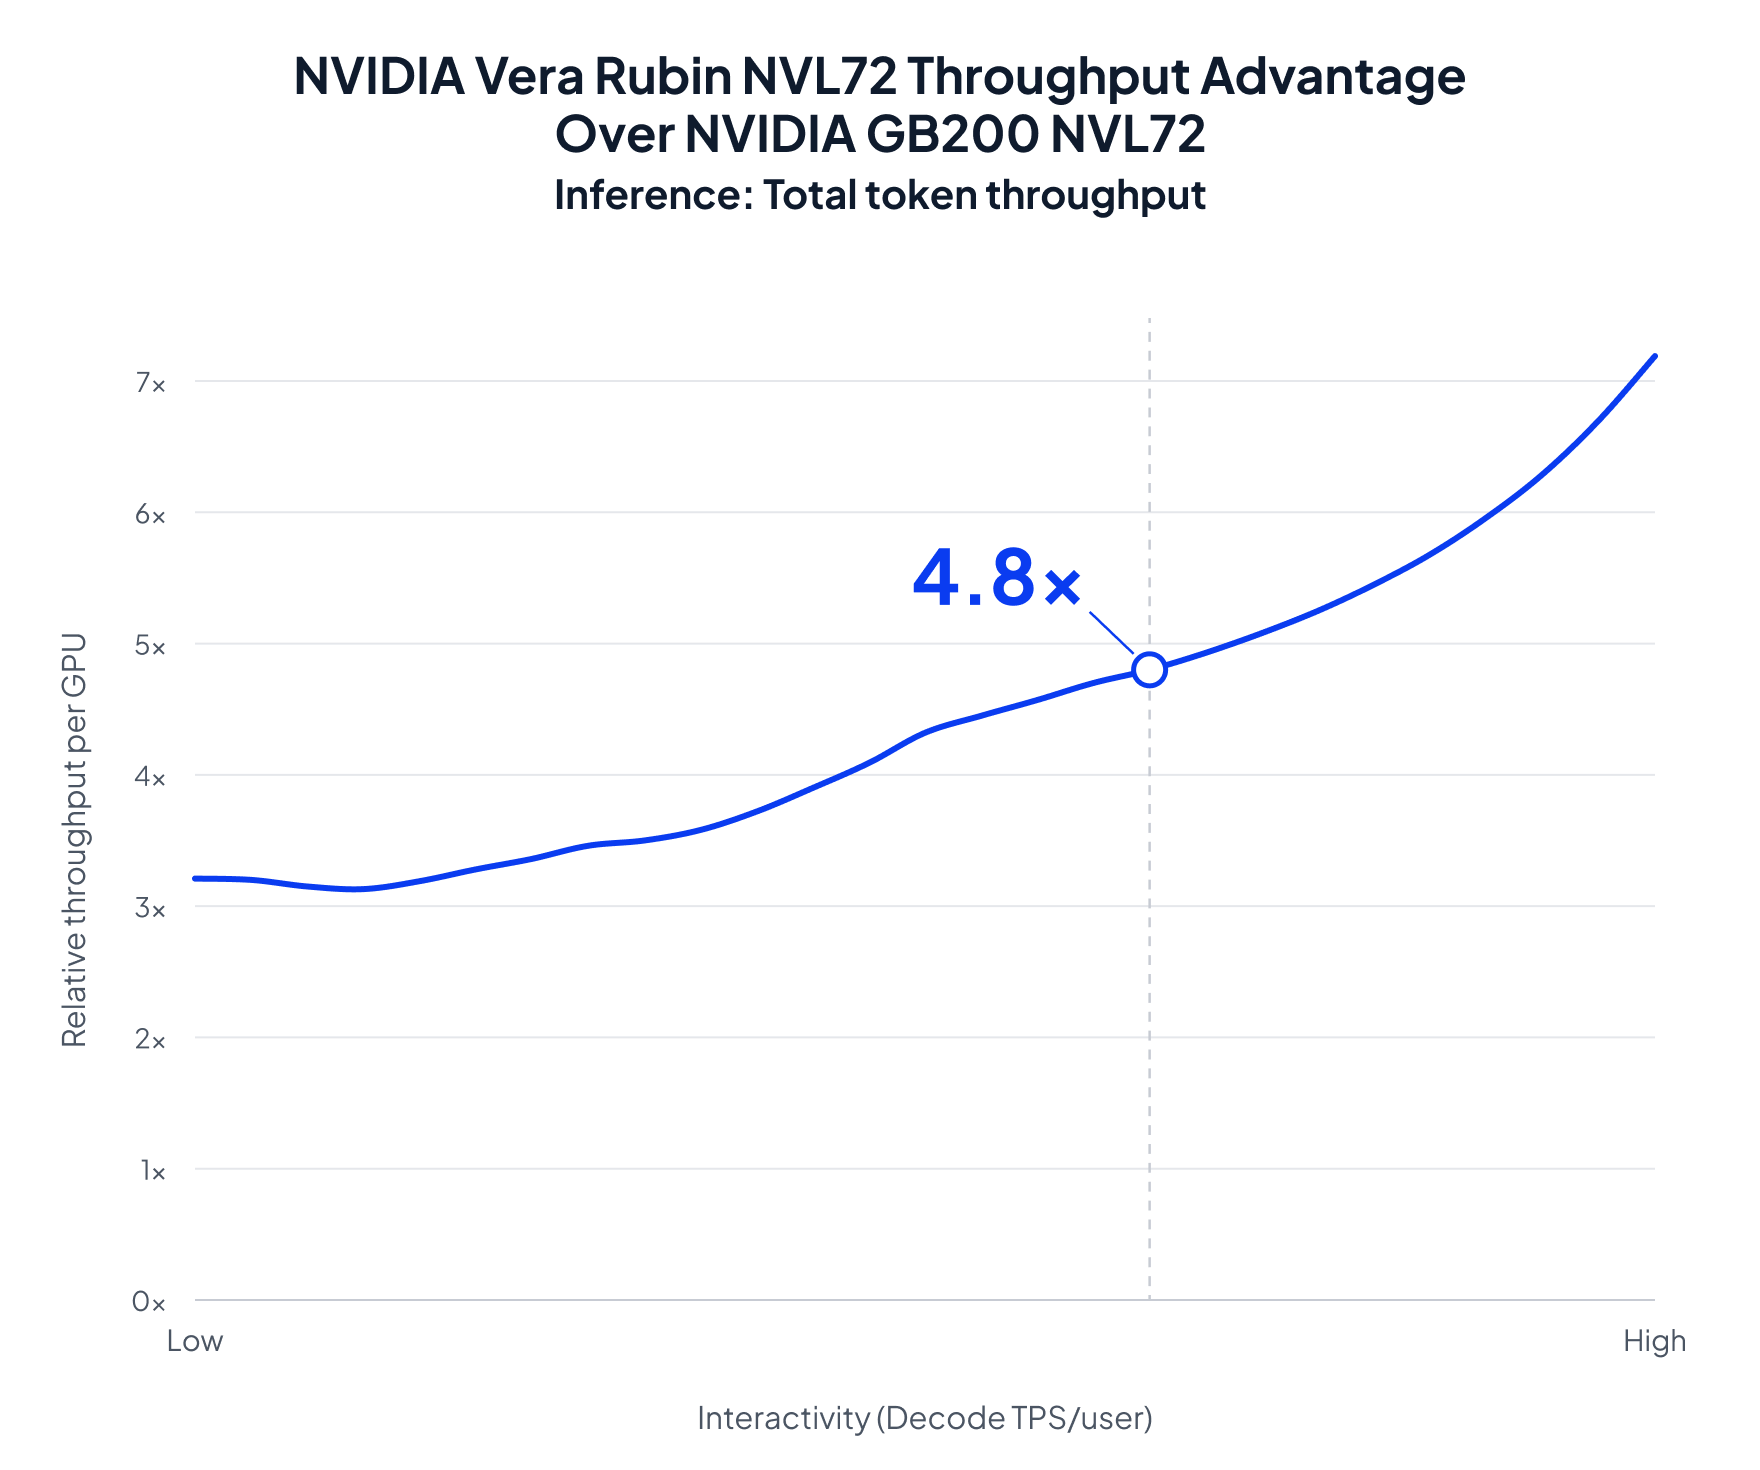
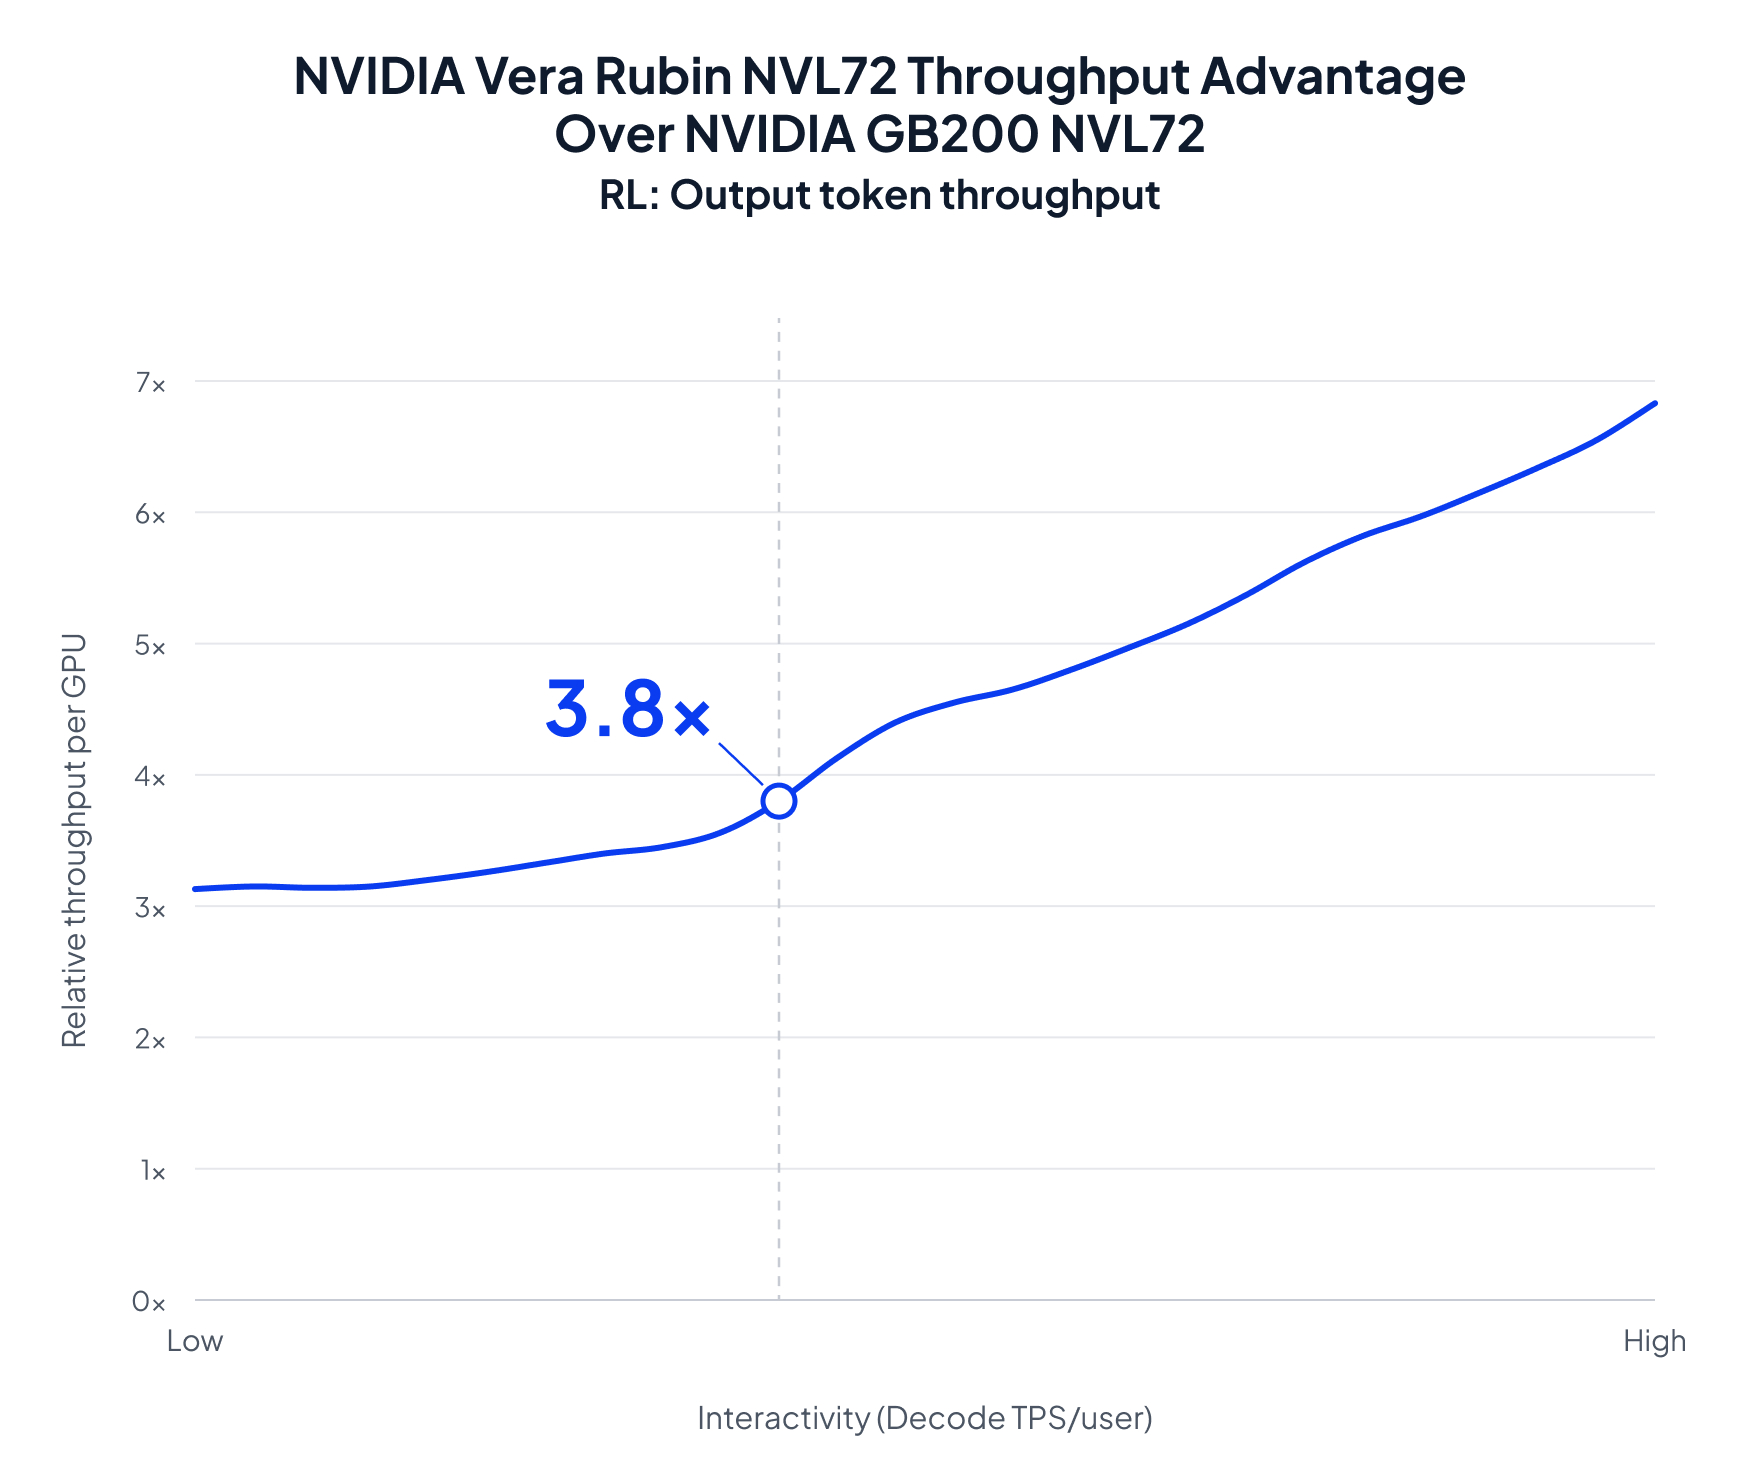
These results show not only how quickly Vera Rubin can generate tokens, but how effectively it can perform and sustain responsive inference as agentic workloads scale.
Vera Rubin is ready for production on CoreWeave Cloud
NVIDIA Vera Rubin NVL72 is no longer just a roadmap or an engineering milestone. It’s here, on CoreWeave Cloud, integrated with our purpose-built AI platform, and ready to run production workloads for select customers. Cognition’s ability to begin running workloads within days of rack handover demonstrates what production readiness looks like: advanced infrastructure delivered without requiring customers to engineer the underlying environment themselves.
Start planning your NVIDIA Vera Rubin deployment. Request a briefing for capacity planning, onboarding timeline, and workload fit — or request an ARENA Pass to run your workload on Vera Rubin NVL72 yourself.
Want to go deeper? Explore our related resources:
- Engineered for Agentic AI: Exploring NVIDIA Vera Rubin on CoreWeave
- A Deep Dive on CoreWeave Innovations for NVIDIA Vera Rubin NVL72
- Liquid-Cooled Switching Doubles AI Network Bandwidth Per Rack
- 5 Lessons from Building a Multi-Plane Network Fabric for Agentic AI
- What It Takes to Bring Up a Multi-Rack NVIDIA Vera Rubin NVL72 Cluster